

Note
Go to the end to download the full example code.
SKD005 - Underrepresented classes#
SKD005 flags a multiclass task when one or more classes each represent less than 10 % of rows. Overall accuracy can look acceptable while rare labels are barely learned. This notebook is about how to work with that rarity once the check fires: we do not try to make SKD005 disappear by reshaping the class histogram.
What to do instead:
report absolute counts as well as percentages,
evaluate threshold-free / probabilistic metrics (such as log-loss) before per class precision and accuracy,
collect more rare-class labels when possible, without treating a cleared check as success,
correct for prevalence shift if acquisition oversamples rare types.
For binary rare-event tasks (threshold tuning, when class_weight is a risky
shortcut), see SKD004 - High class imbalance and:
https://probabl-ai.github.io/calibration-cost-sensitive-learning/content/notebooks/imbalanced_classification.html
We take a 10,000-row stratified subsample of Covertype so several forest types fall below 10 %. The goal is to keep natural prevalence visible, judge the multiclass model honestly, then see what extra rare-class rows can do.
Load the Covertype dataset#
The full Covertype task has seven forest types. A small stratified subsample keeps frequent classes well represented while types 3-7 drop below 10 % each. We keep the unused rows as a pool for the “more rare-class data” section later.
import pandas as pd
from sklearn.datasets import fetch_covtype
from sklearn.model_selection import train_test_split

df = fetch_covtype(as_frame=True).frame
y_full = df["Cover_Type"].astype(str)
X_full = df.drop(columns=["Cover_Type"])

X, X_pool, y, y_pool = train_test_split(
    X_full,
    y_full,
    train_size=10_000,
    stratify=y_full,
    random_state=42,
)
y, y_pool = y.rename("class"), y_pool.rename("class")
Let us inspect the feature matrix with TableReport.
from skrub import TableReport

TableReport(X)
| Elevation | Aspect | Slope | Horizontal_Distance_To_Hydrology | Vertical_Distance_To_Hydrology | Horizontal_Distance_To_Roadways | Hillshade_9am | Hillshade_Noon | Hillshade_3pm | Horizontal_Distance_To_Fire_Points | Wilderness_Area_0 | Wilderness_Area_1 | Wilderness_Area_2 | Wilderness_Area_3 | Soil_Type_0 | Soil_Type_1 | Soil_Type_2 | Soil_Type_3 | Soil_Type_4 | Soil_Type_5 | Soil_Type_6 | Soil_Type_7 | Soil_Type_8 | Soil_Type_9 | Soil_Type_10 | Soil_Type_11 | Soil_Type_12 | Soil_Type_13 | Soil_Type_14 | Soil_Type_15 | Soil_Type_16 | Soil_Type_17 | Soil_Type_18 | Soil_Type_19 | Soil_Type_20 | Soil_Type_21 | Soil_Type_22 | Soil_Type_23 | Soil_Type_24 | Soil_Type_25 | Soil_Type_26 | Soil_Type_27 | Soil_Type_28 | Soil_Type_29 | Soil_Type_30 | Soil_Type_31 | Soil_Type_32 | Soil_Type_33 | Soil_Type_34 | Soil_Type_35 | Soil_Type_36 | Soil_Type_37 | Soil_Type_38 | Soil_Type_39 | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 333,153 | 2.77e+03 | 101. | 11.0 | 300. | 14.0 | 808. | 239. | 225. | 115. | 543. | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
| 73,090 | 3.08e+03 | 104. | 10.0 | 67.0 | 0.00 | 3.01e+03 | 238. | 227. | 119. | 5.63e+03 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
| 559,685 | 2.53e+03 | 156. | 20.0 | 30.0 | -9.00 | 1.57e+03 | 238. | 238. | 119. | 1.44e+03 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
| 221,753 | 2.46e+03 | 275. | 17.0 | 234. | 64.0 | 391. | 172. | 242. | 208. | 1.34e+03 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
| 428,256 | 3.05e+03 | 34.0 | 14.0 | 960. | 227. | 1.21e+03 | 217. | 207. | 122. | 2.46e+03 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
| 300,351 | 3.04e+03 | 39.0 | 7.00 | 480. | -1.00 | 3.21e+03 | 221. | 225. | 140. | 1.02e+03 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
| 135,386 | 2.64e+03 | 13.0 | 8.00 | 390. | -1.00 | 992. | 212. | 223. | 148. | 309. | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
| 132,505 | 2.64e+03 | 50.0 | 16.0 | 153. | 12.0 | 1.21e+03 | 225. | 204. | 108. | 108. | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
| 494,080 | 2.78e+03 | 144. | 20.0 | 0.00 | 0.00 | 702. | 244. | 232. | 107. | 899. | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
| 105,915 | 3.08e+03 | 49.0 | 16.0 | 342. | 0.00 | 3.89e+03 | 225. | 203. | 108. | 3.65e+03 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
Elevation
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
1,375 (13.8%)
This column has a high cardinality (> 40).
- Mean ± Std
- 2.96e+03 ± 280.
- Median ± IQR
- 3.00e+03 ± 356.
- Min | Max
- 1.88e+03 | 3.86e+03
Aspect
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
361 (3.6%)
This column has a high cardinality (> 40).
- Mean ± Std
- 157. ± 112.
- Median ± IQR
- 128. ± 205.
- Min | Max
- 0.00 | 360.
Slope
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
50 (0.5%)
This column has a high cardinality (> 40).
- Mean ± Std
- 14.2 ± 7.48
- Median ± IQR
- 13.0 ± 10.0
- Min | Max
- 0.00 | 51.0
Horizontal_Distance_To_Hydrology
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
367 (3.7%)
This column has a high cardinality (> 40).
- Mean ± Std
- 270. ± 213.
- Median ± IQR
- 218. ± 282.
- Min | Max
- 0.00 | 1.34e+03
Vertical_Distance_To_Hydrology
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
418 (4.2%)
This column has a high cardinality (> 40).
- Mean ± Std
- 47.6 ± 59.8
- Median ± IQR
- 30.0 ± 65.0
- Min | Max
- -152. | 544.
Horizontal_Distance_To_Roadways
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
3,489 (34.9%)
This column has a high cardinality (> 40).
- Mean ± Std
- 2.34e+03 ± 1.55e+03
- Median ± IQR
- 2.01e+03 ± 2.19e+03
- Min | Max
- 0.00 | 7.04e+03
Hillshade_9am
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
170 (1.7%)
This column has a high cardinality (> 40).
- Mean ± Std
- 212. ± 27.2
- Median ± IQR
- 217. ± 33.0
- Min | Max
- 0.00 | 254.
Hillshade_Noon
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
126 (1.3%)
This column has a high cardinality (> 40).
- Mean ± Std
- 223. ± 19.5
- Median ± IQR
- 226. ± 24.0
- Min | Max
- 100. | 254.
Hillshade_3pm
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
235 (2.4%)
This column has a high cardinality (> 40).
- Mean ± Std
- 143. ± 38.5
- Median ± IQR
- 143. ± 50.0
- Min | Max
- 0.00 | 248.
Horizontal_Distance_To_Fire_Points
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
2,938 (29.4%)
This column has a high cardinality (> 40).
- Mean ± Std
- 1.97e+03 ± 1.32e+03
- Median ± IQR
- 1.68e+03 ± 1.50e+03
- Min | Max
- 0.00 | 6.93e+03
Wilderness_Area_0
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.445 ± 0.497
- Median ± IQR
- 0.00 ± 1.00
- Min | Max
- 0.00 | 1.00
Wilderness_Area_1
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0491 ± 0.216
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Wilderness_Area_2
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.441 ± 0.497
- Median ± IQR
- 0.00 ± 1.00
- Min | Max
- 0.00 | 1.00
Wilderness_Area_3
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0650 ± 0.247
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_0
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00530 ± 0.0726
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_1
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0140 ± 0.117
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_2
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00680 ± 0.0822
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_3
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0220 ± 0.147
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_4
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00300 ± 0.0547
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_5
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0124 ± 0.111
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_6
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.000200 ± 0.0141
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_7
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.000400 ± 0.0200
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_8
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00160 ± 0.0400
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_9
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0551 ± 0.228
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_10
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0230 ± 0.150
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_11
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0518 ± 0.222
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_12
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0318 ± 0.175
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_13
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00140 ± 0.0374
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_14
Float64DType- Null values
- 0 (0.0%)
Soil_Type_15
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00520 ± 0.0719
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_16
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00610 ± 0.0779
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_17
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00440 ± 0.0662
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_18
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00620 ± 0.0785
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_19
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0145 ± 0.120
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_20
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00190 ± 0.0435
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_21
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0560 ± 0.230
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_22
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0991 ± 0.299
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_23
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0360 ± 0.186
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_24
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.000600 ± 0.0245
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_25
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00560 ± 0.0746
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_26
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00160 ± 0.0400
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_27
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00160 ± 0.0400
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_28
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.195 ± 0.396
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_29
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0526 ± 0.223
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_30
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0447 ± 0.207
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_31
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0890 ± 0.285
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_32
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0819 ± 0.274
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_33
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00330 ± 0.0574
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_34
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00360 ± 0.0599
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_35
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.000400 ± 0.0200
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_36
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.000400 ± 0.0200
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_37
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0217 ± 0.146
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_38
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0239 ± 0.153
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_39
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0157 ± 0.124
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
No columns match the selected filter: . You can change the column filter in the dropdown menu above.
| Column | Column name | dtype | Is sorted | Null values | Unique values | Mean | Std | Min | Median | Max |
|---|---|---|---|---|---|---|---|---|---|---|
| 0 | Elevation | Float64DType | False | 0 (0.0%) | 1375 (13.8%) | 2.96e+03 | 280. | 1.88e+03 | 3.00e+03 | 3.86e+03 |
| 1 | Aspect | Float64DType | False | 0 (0.0%) | 361 (3.6%) | 157. | 112. | 0.00 | 128. | 360. |
| 2 | Slope | Float64DType | False | 0 (0.0%) | 50 (0.5%) | 14.2 | 7.48 | 0.00 | 13.0 | 51.0 |
| 3 | Horizontal_Distance_To_Hydrology | Float64DType | False | 0 (0.0%) | 367 (3.7%) | 270. | 213. | 0.00 | 218. | 1.34e+03 |
| 4 | Vertical_Distance_To_Hydrology | Float64DType | False | 0 (0.0%) | 418 (4.2%) | 47.6 | 59.8 | -152. | 30.0 | 544. |
| 5 | Horizontal_Distance_To_Roadways | Float64DType | False | 0 (0.0%) | 3489 (34.9%) | 2.34e+03 | 1.55e+03 | 0.00 | 2.01e+03 | 7.04e+03 |
| 6 | Hillshade_9am | Float64DType | False | 0 (0.0%) | 170 (1.7%) | 212. | 27.2 | 0.00 | 217. | 254. |
| 7 | Hillshade_Noon | Float64DType | False | 0 (0.0%) | 126 (1.3%) | 223. | 19.5 | 100. | 226. | 254. |
| 8 | Hillshade_3pm | Float64DType | False | 0 (0.0%) | 235 (2.4%) | 143. | 38.5 | 0.00 | 143. | 248. |
| 9 | Horizontal_Distance_To_Fire_Points | Float64DType | False | 0 (0.0%) | 2938 (29.4%) | 1.97e+03 | 1.32e+03 | 0.00 | 1.68e+03 | 6.93e+03 |
| 10 | Wilderness_Area_0 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.445 | 0.497 | 0.00 | 0.00 | 1.00 |
| 11 | Wilderness_Area_1 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0491 | 0.216 | 0.00 | 0.00 | 1.00 |
| 12 | Wilderness_Area_2 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.441 | 0.497 | 0.00 | 0.00 | 1.00 |
| 13 | Wilderness_Area_3 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0650 | 0.247 | 0.00 | 0.00 | 1.00 |
| 14 | Soil_Type_0 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00530 | 0.0726 | 0.00 | 0.00 | 1.00 |
| 15 | Soil_Type_1 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0140 | 0.117 | 0.00 | 0.00 | 1.00 |
| 16 | Soil_Type_2 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00680 | 0.0822 | 0.00 | 0.00 | 1.00 |
| 17 | Soil_Type_3 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0220 | 0.147 | 0.00 | 0.00 | 1.00 |
| 18 | Soil_Type_4 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00300 | 0.0547 | 0.00 | 0.00 | 1.00 |
| 19 | Soil_Type_5 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0124 | 0.111 | 0.00 | 0.00 | 1.00 |
| 20 | Soil_Type_6 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.000200 | 0.0141 | 0.00 | 0.00 | 1.00 |
| 21 | Soil_Type_7 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.000400 | 0.0200 | 0.00 | 0.00 | 1.00 |
| 22 | Soil_Type_8 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00160 | 0.0400 | 0.00 | 0.00 | 1.00 |
| 23 | Soil_Type_9 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0551 | 0.228 | 0.00 | 0.00 | 1.00 |
| 24 | Soil_Type_10 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0230 | 0.150 | 0.00 | 0.00 | 1.00 |
| 25 | Soil_Type_11 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0518 | 0.222 | 0.00 | 0.00 | 1.00 |
| 26 | Soil_Type_12 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0318 | 0.175 | 0.00 | 0.00 | 1.00 |
| 27 | Soil_Type_13 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00140 | 0.0374 | 0.00 | 0.00 | 1.00 |
| 28 | Soil_Type_14 | Float64DType | True | 0 (0.0%) | 1 (< 0.1%) | 0.00 | 0.00 | |||
| 29 | Soil_Type_15 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00520 | 0.0719 | 0.00 | 0.00 | 1.00 |
| 30 | Soil_Type_16 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00610 | 0.0779 | 0.00 | 0.00 | 1.00 |
| 31 | Soil_Type_17 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00440 | 0.0662 | 0.00 | 0.00 | 1.00 |
| 32 | Soil_Type_18 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00620 | 0.0785 | 0.00 | 0.00 | 1.00 |
| 33 | Soil_Type_19 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0145 | 0.120 | 0.00 | 0.00 | 1.00 |
| 34 | Soil_Type_20 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00190 | 0.0435 | 0.00 | 0.00 | 1.00 |
| 35 | Soil_Type_21 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0560 | 0.230 | 0.00 | 0.00 | 1.00 |
| 36 | Soil_Type_22 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0991 | 0.299 | 0.00 | 0.00 | 1.00 |
| 37 | Soil_Type_23 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0360 | 0.186 | 0.00 | 0.00 | 1.00 |
| 38 | Soil_Type_24 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.000600 | 0.0245 | 0.00 | 0.00 | 1.00 |
| 39 | Soil_Type_25 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00560 | 0.0746 | 0.00 | 0.00 | 1.00 |
| 40 | Soil_Type_26 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00160 | 0.0400 | 0.00 | 0.00 | 1.00 |
| 41 | Soil_Type_27 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00160 | 0.0400 | 0.00 | 0.00 | 1.00 |
| 42 | Soil_Type_28 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.195 | 0.396 | 0.00 | 0.00 | 1.00 |
| 43 | Soil_Type_29 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0526 | 0.223 | 0.00 | 0.00 | 1.00 |
| 44 | Soil_Type_30 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0447 | 0.207 | 0.00 | 0.00 | 1.00 |
| 45 | Soil_Type_31 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0890 | 0.285 | 0.00 | 0.00 | 1.00 |
| 46 | Soil_Type_32 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0819 | 0.274 | 0.00 | 0.00 | 1.00 |
| 47 | Soil_Type_33 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00330 | 0.0574 | 0.00 | 0.00 | 1.00 |
| 48 | Soil_Type_34 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00360 | 0.0599 | 0.00 | 0.00 | 1.00 |
| 49 | Soil_Type_35 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.000400 | 0.0200 | 0.00 | 0.00 | 1.00 |
| 50 | Soil_Type_36 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.000400 | 0.0200 | 0.00 | 0.00 | 1.00 |
| 51 | Soil_Type_37 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0217 | 0.146 | 0.00 | 0.00 | 1.00 |
| 52 | Soil_Type_38 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0239 | 0.153 | 0.00 | 0.00 | 1.00 |
| 53 | Soil_Type_39 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0157 | 0.124 | 0.00 | 0.00 | 1.00 |
No columns match the selected filter: . You can change the column filter in the dropdown menu above.
Plotting was skipped. This is due to either:
- The dataframe exceeding the configured
table_report_plots_thresholdlimit (default: 30). - The
plot_distributionsoption being set toFalse(default:"auto", which applies the configuredtable_report_plots_threshold).
You can adjust this behavior in several ways:
- To force plotting for a single report:
report = TableReport(df, plot_distributions=True) - To change the threshold for the current Python session, use
skrub.set_config:from skrub import set_config set_config(table_report_plots_threshold=50) - To make the change permanent, use an environment variable:
export SKB_TABLE_REPORT_PLOTS_THRESHOLD=50
No columns match the selected filter: . You can change the column filter in the dropdown menu above.
Computing pairwise associations was skipped. This is due to either:
- The dataframe exceeding the configured
table_report_associations_thresholdlimit (default: 30). - The
compute_associationsoption being set toFalse(default:"auto", which applies the configuredtable_report_associations_threshold).
You can adjust this behavior in several ways:
- To force computation for a single report:
report = TableReport(df, compute_associations=True) - To change the threshold for the current Python session, use
skrub.set_config:from skrub import set_config set_config(table_report_associations_threshold=50) - To make the change permanent, use an environment variable:
export SKB_TABLE_REPORT_ASSOCIATIONS_THRESHOLD=50
Please enable javascript
The skrub table reports need javascript to display correctly. If you are displaying a report in a Jupyter notebook and you see this message, you may need to re-execute the cell or to trust the notebook (button on the top right or "File > Trust notebook").
Clicking the column in the target’s TableReport brings
a class histogram that shows that the classes are not evenly distributed.
Let us also look at absolute counts: type 4 is under 1 % with only a few dozen rows in this subsample: even a good multiclass model has little to learn from there. Types such as 6 are also under the 10 % SKD005 bar, but with a few hundred rows they are less hopeless.
shares = y.value_counts(normalize=True).sort_index()
counts = y.value_counts().sort_index()
pd.concat([shares.round(4), counts], axis=1)
Trigger SKD005: default classifier on imbalanced classes#
A default gradient boosting classifier does not change label counts. We ignore SKD008 to avoid correlated-feature warnings from Covertype’s constant soil one-hots.
import skore
from sklearn.ensemble import HistGradientBoostingClassifier
from skore import TrainTestSplit

splitter = TrainTestSplit(test_size=0.2, random_state=42, stratify=y)
classifier = HistGradientBoostingClassifier(random_state=42)

report = skore.evaluate(
    classifier,
    X=X,
    y=y,
    splitter=splitter,
)
report
| Metric | Label | Average | HistGradientBoostingClassifier |
|---|---|---|---|
| Accuracy | 0.738000 | ||
| Precision | 1 | 0.765805 | |
| Precision | 2 | 0.783453 | |
| Precision | 3 | 0.674419 | |
| Precision | 4 | 0.250000 | |
| Precision | 5 | 0.270270 | |
| Precision | 6 | 0.372881 | |
| Precision | 7 | 0.650000 | |
| Precision | macro | 0.538118 | |
| Recall | 1 | 0.731139 | |
| Recall | 2 | 0.786667 | |
| Recall | 3 | 0.707317 | |
| Recall | 4 | 0.555556 | |
| Recall | 5 | 0.303030 | |
| Recall | 6 | 0.366667 | |
| Recall | 7 | 0.732394 | |
| Recall | macro | 0.597538 | |
| ROC AUC | 1 | 0.862669 | |
| ROC AUC | 2 | 0.833460 | |
| ROC AUC | 3 | 0.901625 | |
| ROC AUC | 4 | 0.881271 | |
| ROC AUC | 5 | 0.776972 | |
| ROC AUC | 6 | 0.853458 | |
| ROC AUC | 7 | 0.951255 | |
| ROC AUC | macro | 0.865816 | |
| Log loss | 2.991535 | ||
| Fit time (s) | 5.212368 | ||
| Predict time (s) | 0.099938 |
- [SKD001] Potential overfitting. Significant train/test gaps were found for 24/26 default predictive metrics.
- [SKD005] Underrepresented classes. Classes ['7', '6', '3', '5', '4'] each represent less than 10% of the dataset samples. Accuracy should not be used alone to assess model performance as it may be misleading by ignoring poor performance on underrepresented classes.
- [SKD016] Estimator not tuned. Estimator(s) left at default settings; consider tuning: ['learning_rate', 'max_leaf_nodes'] for HistGradientBoostingClassifier.
- [SKD003] Inconsistent performance across splits. Not applicable to estimator reports.
- [SKD004] High class imbalance. ML task is not binary classification. Got multiclass-classification.
- [SKD006] Coefficient interpretation. Estimator is not a linear model: it does not have a `coef_` attribute.
- [SKD007] MDI biased for high-cardinality features. Estimator is not a tree-based model: it does not have a `feature_importances_` attribute.
- [SKD013] Train-test overlap in time series. No datetime column found.
- [SKD014] Hyperparameters at search edge. Estimator is not a BaseSearchCV instance. Got HistGradientBoostingClassifier.
- [SKD015] Hyperparameters worth tuning. Estimator is not a BaseSearchCV instance. Got HistGradientBoostingClassifier.
No checks were muted.
Fast mode is on: expensive checks are skipped unless already cached.
Mute a check by passing its code to ignore, e.g. .checks.summarize(ignore=['SKD001']).
HistGradientBoostingClassifier(random_state=42)In a Jupyter environment, please rerun this cell to show the HTML representation or trust the notebook.
On GitHub, the HTML representation is unable to render, please try loading this page with nbviewer.org.
Parameters
Fitted attributes
| Elevation | Aspect | Slope | Horizontal_Distance_To_Hydrology | Vertical_Distance_To_Hydrology | Horizontal_Distance_To_Roadways | Hillshade_9am | Hillshade_Noon | Hillshade_3pm | Horizontal_Distance_To_Fire_Points | Wilderness_Area_0 | Wilderness_Area_1 | Wilderness_Area_2 | Wilderness_Area_3 | Soil_Type_0 | Soil_Type_1 | Soil_Type_2 | Soil_Type_3 | Soil_Type_4 | Soil_Type_5 | Soil_Type_6 | Soil_Type_7 | Soil_Type_8 | Soil_Type_9 | Soil_Type_10 | Soil_Type_11 | Soil_Type_12 | Soil_Type_13 | Soil_Type_14 | Soil_Type_15 | Soil_Type_16 | Soil_Type_17 | Soil_Type_18 | Soil_Type_19 | Soil_Type_20 | Soil_Type_21 | Soil_Type_22 | Soil_Type_23 | Soil_Type_24 | Soil_Type_25 | Soil_Type_26 | Soil_Type_27 | Soil_Type_28 | Soil_Type_29 | Soil_Type_30 | Soil_Type_31 | Soil_Type_32 | Soil_Type_33 | Soil_Type_34 | Soil_Type_35 | Soil_Type_36 | Soil_Type_37 | Soil_Type_38 | Soil_Type_39 | class | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 3.21e+03 | 62.0 | 13.0 | 85.0 | 3.00 | 3.27e+03 | 230. | 213. | 113. | 3.97e+03 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 1 |
| 1 | 2.82e+03 | 79.0 | 4.00 | 0.00 | 0.00 | 4.58e+03 | 224. | 233. | 144. | 4.75e+03 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 2 |
| 2 | 2.98e+03 | 42.0 | 7.00 | 30.0 | 2.00 | 1.03e+03 | 222. | 224. | 137. | 1.40e+03 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1 |
| 3 | 3.24e+03 | 107. | 15.0 | 60.0 | 4.00 | 2.36e+03 | 244. | 221. | 103. | 558. | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 7 |
| 4 | 3.00e+03 | 45.0 | 5.00 | 330. | 57.0 | 1.25e+03 | 221. | 229. | 143. | 680. | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1 |
| 9,995 | 2.61e+03 | 21.0 | 15.0 | 384. | 4.00 | 1.84e+03 | 208. | 206. | 131. | 2.12e+03 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 2 |
| 9,996 | 3.25e+03 | 359. | 11.0 | 459. | 101. | 902. | 203. | 220. | 154. | 2.06e+03 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 2 |
| 9,997 | 3.11e+03 | 354. | 4.00 | 306. | 22.0 | 1.38e+03 | 212. | 232. | 157. | 1.35e+03 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 2 |
| 9,998 | 3.15e+03 | 102. | 10.0 | 150. | -15.0 | 3.36e+03 | 237. | 227. | 120. | 4.96e+03 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1 |
| 9,999 | 2.82e+03 | 235. | 11.0 | 162. | 3.00 | 934. | 200. | 250. | 187. | 272. | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 1 |
Elevation
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
1,375 (13.8%)
This column has a high cardinality (> 40).
- Mean ± Std
- 2.96e+03 ± 280.
- Median ± IQR
- 3.00e+03 ± 356.
- Min | Max
- 1.88e+03 | 3.86e+03
Aspect
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
361 (3.6%)
This column has a high cardinality (> 40).
- Mean ± Std
- 157. ± 112.
- Median ± IQR
- 128. ± 205.
- Min | Max
- 0.00 | 360.
Slope
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
50 (0.5%)
This column has a high cardinality (> 40).
- Mean ± Std
- 14.2 ± 7.48
- Median ± IQR
- 13.0 ± 10.0
- Min | Max
- 0.00 | 51.0
Horizontal_Distance_To_Hydrology
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
367 (3.7%)
This column has a high cardinality (> 40).
- Mean ± Std
- 270. ± 213.
- Median ± IQR
- 218. ± 282.
- Min | Max
- 0.00 | 1.34e+03
Vertical_Distance_To_Hydrology
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
418 (4.2%)
This column has a high cardinality (> 40).
- Mean ± Std
- 47.6 ± 59.8
- Median ± IQR
- 30.0 ± 65.0
- Min | Max
- -152. | 544.
Horizontal_Distance_To_Roadways
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
3,489 (34.9%)
This column has a high cardinality (> 40).
- Mean ± Std
- 2.34e+03 ± 1.55e+03
- Median ± IQR
- 2.01e+03 ± 2.19e+03
- Min | Max
- 0.00 | 7.04e+03
Hillshade_9am
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
170 (1.7%)
This column has a high cardinality (> 40).
- Mean ± Std
- 212. ± 27.2
- Median ± IQR
- 217. ± 33.0
- Min | Max
- 0.00 | 254.
Hillshade_Noon
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
126 (1.3%)
This column has a high cardinality (> 40).
- Mean ± Std
- 223. ± 19.5
- Median ± IQR
- 226. ± 24.0
- Min | Max
- 100. | 254.
Hillshade_3pm
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
235 (2.4%)
This column has a high cardinality (> 40).
- Mean ± Std
- 143. ± 38.5
- Median ± IQR
- 143. ± 50.0
- Min | Max
- 0.00 | 248.
Horizontal_Distance_To_Fire_Points
Float64DType- Null values
- 0 (0.0%)
- Unique values
-
2,938 (29.4%)
This column has a high cardinality (> 40).
- Mean ± Std
- 1.97e+03 ± 1.32e+03
- Median ± IQR
- 1.68e+03 ± 1.50e+03
- Min | Max
- 0.00 | 6.93e+03
Wilderness_Area_0
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.445 ± 0.497
- Median ± IQR
- 0.00 ± 1.00
- Min | Max
- 0.00 | 1.00
Wilderness_Area_1
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0491 ± 0.216
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Wilderness_Area_2
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.441 ± 0.497
- Median ± IQR
- 0.00 ± 1.00
- Min | Max
- 0.00 | 1.00
Wilderness_Area_3
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0650 ± 0.247
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_0
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00530 ± 0.0726
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_1
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0140 ± 0.117
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_2
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00680 ± 0.0822
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_3
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0220 ± 0.147
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_4
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00300 ± 0.0547
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_5
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0124 ± 0.111
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_6
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.000200 ± 0.0141
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_7
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.000400 ± 0.0200
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_8
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00160 ± 0.0400
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_9
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0551 ± 0.228
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_10
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0230 ± 0.150
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_11
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0518 ± 0.222
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_12
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0318 ± 0.175
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_13
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00140 ± 0.0374
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_14
Float64DType- Null values
- 0 (0.0%)
Soil_Type_15
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00520 ± 0.0719
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_16
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00610 ± 0.0779
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_17
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00440 ± 0.0662
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_18
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00620 ± 0.0785
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_19
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0145 ± 0.120
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_20
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00190 ± 0.0435
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_21
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0560 ± 0.230
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_22
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0991 ± 0.299
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_23
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0360 ± 0.186
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_24
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.000600 ± 0.0245
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_25
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00560 ± 0.0746
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_26
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00160 ± 0.0400
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_27
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00160 ± 0.0400
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_28
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.195 ± 0.396
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_29
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0526 ± 0.223
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_30
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0447 ± 0.207
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_31
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0890 ± 0.285
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_32
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0819 ± 0.274
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_33
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00330 ± 0.0574
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_34
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.00360 ± 0.0599
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_35
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.000400 ± 0.0200
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_36
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.000400 ± 0.0200
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_37
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0217 ± 0.146
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_38
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0239 ± 0.153
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
Soil_Type_39
Float64DType- Null values
- 0 (0.0%)
- Unique values
- 2 (< 0.1%)
- Mean ± Std
- 0.0157 ± 0.124
- Median ± IQR
- 0.00 ± 0.00
- Min | Max
- 0.00 | 1.00
class
ObjectDType- Null values
- 0 (0.0%)
- Unique values
- 7 (< 0.1%)
No columns match the selected filter: . You can change the column filter in the dropdown menu above.
| Column | Column name | dtype | Is sorted | Null values | Unique values | Mean | Std | Min | Median | Max |
|---|---|---|---|---|---|---|---|---|---|---|
| 0 | Elevation | Float64DType | False | 0 (0.0%) | 1375 (13.8%) | 2.96e+03 | 280. | 1.88e+03 | 3.00e+03 | 3.86e+03 |
| 1 | Aspect | Float64DType | False | 0 (0.0%) | 361 (3.6%) | 157. | 112. | 0.00 | 128. | 360. |
| 2 | Slope | Float64DType | False | 0 (0.0%) | 50 (0.5%) | 14.2 | 7.48 | 0.00 | 13.0 | 51.0 |
| 3 | Horizontal_Distance_To_Hydrology | Float64DType | False | 0 (0.0%) | 367 (3.7%) | 270. | 213. | 0.00 | 218. | 1.34e+03 |
| 4 | Vertical_Distance_To_Hydrology | Float64DType | False | 0 (0.0%) | 418 (4.2%) | 47.6 | 59.8 | -152. | 30.0 | 544. |
| 5 | Horizontal_Distance_To_Roadways | Float64DType | False | 0 (0.0%) | 3489 (34.9%) | 2.34e+03 | 1.55e+03 | 0.00 | 2.01e+03 | 7.04e+03 |
| 6 | Hillshade_9am | Float64DType | False | 0 (0.0%) | 170 (1.7%) | 212. | 27.2 | 0.00 | 217. | 254. |
| 7 | Hillshade_Noon | Float64DType | False | 0 (0.0%) | 126 (1.3%) | 223. | 19.5 | 100. | 226. | 254. |
| 8 | Hillshade_3pm | Float64DType | False | 0 (0.0%) | 235 (2.4%) | 143. | 38.5 | 0.00 | 143. | 248. |
| 9 | Horizontal_Distance_To_Fire_Points | Float64DType | False | 0 (0.0%) | 2938 (29.4%) | 1.97e+03 | 1.32e+03 | 0.00 | 1.68e+03 | 6.93e+03 |
| 10 | Wilderness_Area_0 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.445 | 0.497 | 0.00 | 0.00 | 1.00 |
| 11 | Wilderness_Area_1 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0491 | 0.216 | 0.00 | 0.00 | 1.00 |
| 12 | Wilderness_Area_2 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.441 | 0.497 | 0.00 | 0.00 | 1.00 |
| 13 | Wilderness_Area_3 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0650 | 0.247 | 0.00 | 0.00 | 1.00 |
| 14 | Soil_Type_0 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00530 | 0.0726 | 0.00 | 0.00 | 1.00 |
| 15 | Soil_Type_1 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0140 | 0.117 | 0.00 | 0.00 | 1.00 |
| 16 | Soil_Type_2 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00680 | 0.0822 | 0.00 | 0.00 | 1.00 |
| 17 | Soil_Type_3 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0220 | 0.147 | 0.00 | 0.00 | 1.00 |
| 18 | Soil_Type_4 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00300 | 0.0547 | 0.00 | 0.00 | 1.00 |
| 19 | Soil_Type_5 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0124 | 0.111 | 0.00 | 0.00 | 1.00 |
| 20 | Soil_Type_6 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.000200 | 0.0141 | 0.00 | 0.00 | 1.00 |
| 21 | Soil_Type_7 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.000400 | 0.0200 | 0.00 | 0.00 | 1.00 |
| 22 | Soil_Type_8 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00160 | 0.0400 | 0.00 | 0.00 | 1.00 |
| 23 | Soil_Type_9 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0551 | 0.228 | 0.00 | 0.00 | 1.00 |
| 24 | Soil_Type_10 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0230 | 0.150 | 0.00 | 0.00 | 1.00 |
| 25 | Soil_Type_11 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0518 | 0.222 | 0.00 | 0.00 | 1.00 |
| 26 | Soil_Type_12 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0318 | 0.175 | 0.00 | 0.00 | 1.00 |
| 27 | Soil_Type_13 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00140 | 0.0374 | 0.00 | 0.00 | 1.00 |
| 28 | Soil_Type_14 | Float64DType | True | 0 (0.0%) | 1 (< 0.1%) | 0.00 | 0.00 | |||
| 29 | Soil_Type_15 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00520 | 0.0719 | 0.00 | 0.00 | 1.00 |
| 30 | Soil_Type_16 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00610 | 0.0779 | 0.00 | 0.00 | 1.00 |
| 31 | Soil_Type_17 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00440 | 0.0662 | 0.00 | 0.00 | 1.00 |
| 32 | Soil_Type_18 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00620 | 0.0785 | 0.00 | 0.00 | 1.00 |
| 33 | Soil_Type_19 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0145 | 0.120 | 0.00 | 0.00 | 1.00 |
| 34 | Soil_Type_20 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00190 | 0.0435 | 0.00 | 0.00 | 1.00 |
| 35 | Soil_Type_21 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0560 | 0.230 | 0.00 | 0.00 | 1.00 |
| 36 | Soil_Type_22 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0991 | 0.299 | 0.00 | 0.00 | 1.00 |
| 37 | Soil_Type_23 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0360 | 0.186 | 0.00 | 0.00 | 1.00 |
| 38 | Soil_Type_24 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.000600 | 0.0245 | 0.00 | 0.00 | 1.00 |
| 39 | Soil_Type_25 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00560 | 0.0746 | 0.00 | 0.00 | 1.00 |
| 40 | Soil_Type_26 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00160 | 0.0400 | 0.00 | 0.00 | 1.00 |
| 41 | Soil_Type_27 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00160 | 0.0400 | 0.00 | 0.00 | 1.00 |
| 42 | Soil_Type_28 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.195 | 0.396 | 0.00 | 0.00 | 1.00 |
| 43 | Soil_Type_29 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0526 | 0.223 | 0.00 | 0.00 | 1.00 |
| 44 | Soil_Type_30 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0447 | 0.207 | 0.00 | 0.00 | 1.00 |
| 45 | Soil_Type_31 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0890 | 0.285 | 0.00 | 0.00 | 1.00 |
| 46 | Soil_Type_32 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0819 | 0.274 | 0.00 | 0.00 | 1.00 |
| 47 | Soil_Type_33 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00330 | 0.0574 | 0.00 | 0.00 | 1.00 |
| 48 | Soil_Type_34 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.00360 | 0.0599 | 0.00 | 0.00 | 1.00 |
| 49 | Soil_Type_35 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.000400 | 0.0200 | 0.00 | 0.00 | 1.00 |
| 50 | Soil_Type_36 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.000400 | 0.0200 | 0.00 | 0.00 | 1.00 |
| 51 | Soil_Type_37 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0217 | 0.146 | 0.00 | 0.00 | 1.00 |
| 52 | Soil_Type_38 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0239 | 0.153 | 0.00 | 0.00 | 1.00 |
| 53 | Soil_Type_39 | Float64DType | False | 0 (0.0%) | 2 (< 0.1%) | 0.0157 | 0.124 | 0.00 | 0.00 | 1.00 |
| 54 | class | ObjectDType | False | 0 (0.0%) | 7 (< 0.1%) |
No columns match the selected filter: . You can change the column filter in the dropdown menu above.
Please enable javascript
The skrub table reports need javascript to display correctly. If you are displaying a report in a Jupyter notebook and you see this message, you may need to re-execute the cell or to trust the notebook (button on the top right or "File > Trust notebook").
SKD005 correctly flags classes 3, 4, 5, 6, and 7 as under 10 % of rows.
report.checks.summarize(fast_mode=True, ignore=["SKD008"])
Accuracy hides rare-class failures#
Accuracy alone can look strong when frequent classes dominate the table. Let us however report it with per class precision and log-loss. We see that global accuracy hides rare-class failures, such as for types 4 and 5.
report.metrics.summarize(metric=["accuracy", "precision", "log_loss"]).frame(
    flat_index=False
)
metric     label
accuracy            0.738000
precision  1        0.765805
           2        0.783453
           3        0.674419
           4        0.250000
           5        0.270270
           6        0.372881
           7        0.650000
log_loss            2.991535
Name: HistGradientBoostingClassifier, dtype: float64
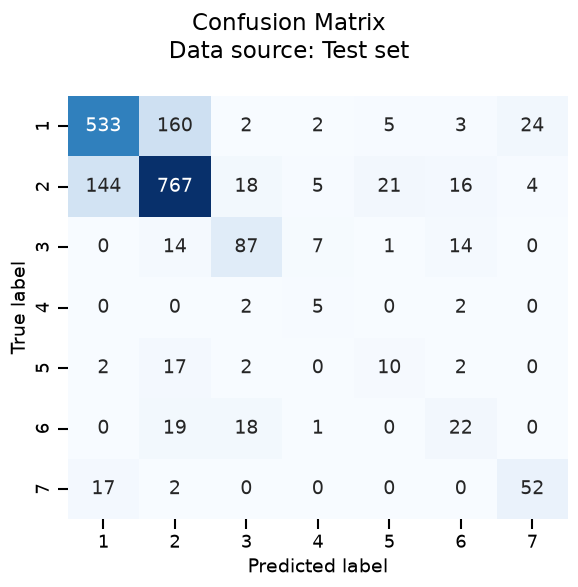
Let us also inspect the confusion matrix. We see that the model has a hard time predicting type 6, often confusing it with types 2 and 3 or when predicting type 7, confusing it with type 1.
report.metrics.confusion_matrix().plot()
<Figure size 600x600 with 1 Axes>
More rare-class training data#
Extra labels on underrepresented types can help the multiclass model see them more often. Let us keep one fixed test fold with the natural mix, fit on the original train fold, then refit after adding rare-class rows from the pool (classes that were under 10 % in the subsample).
X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.2, random_state=42, stratify=y
)

rare_labels = shares[shares < 0.10].index
pool_rare = y_pool.isin(rare_labels)
X_rare_extra, _, y_rare_extra, _ = train_test_split(
    X_pool.loc[pool_rare],
    y_pool.loc[pool_rare],
    train_size=min(5_000, int(pool_rare.sum())),
    stratify=y_pool.loc[pool_rare],
    random_state=42,
)
X_train_more = pd.concat([X_train, X_rare_extra])
y_train_more = pd.concat([y_train, y_rare_extra])

print("Rare labels added from the pool:", list(rare_labels))
print("Extra rare-class rows added:", len(y_rare_extra))
Rare labels added from the pool: ['3', '4', '5', '6', '7']
Extra rare-class rows added: 5000
print("\nBaseline train counts:")
y_train.value_counts().sort_index()
Baseline train counts:

class
1    2917
2    3901
3     492
4      38
5     131
6     239
7     282
Name: count, dtype: int64
print("\nEnriched train counts:")
y_train_more.value_counts().sort_index()
Enriched train counts:

class
1    2917
2    3901
3    2574
4     198
5     684
6    1250
7    1476
Name: count, dtype: int64
Let us now fit a model on the enriched train set and compare the results with the original model. We can observe that the model on the enriched train set has a better log-loss, accuracy and per-class precision on the common test set.
The log-loss is the most importance metric to look at here, as it evaluates the model’s predicted probabilities, which give more robust estimate of the model’s quality. In contrast, accuracy and per-class precision are computed with hard class predictions, obtained from the argmax of the predicted probabilities, which can hide uncalibrated predictions.
model_less = HistGradientBoostingClassifier(random_state=42).fit(X_train, y_train)
report_less = skore.evaluate(model_less, X_test, y_test, splitter="prefit")
report_less